Notation matters: chemistry language models and what is inside them
TL;DR. Ask a language model the water solubility of a molecule written four ways (SMILES, an IUPAC name, an InChI, a SELFIES string) and it will often give four different answers. Across 1,072 molecules, 88% got answers more than 0.5 log S apart, with a mean spread of 1.69 log S; a descriptor model fed the same molecules moved 16× less. Looking inside a small chemistry encoder, the representations of two strings of the same molecule progressively diverge with depth (cosine 0.99 → 0.66). This is a full walk-through of the paper, its numbers, and the caveats.
The assumption nobody tests
Every chemistry-LLM pipeline silently assumes that the model reasons about the molecule and that the notation is just packaging. The paper puts the assumption plainly: “If a model truly internalises molecular concepts, its property predictions should be robust to this choice.” One molecule has many valid written forms, and they look nothing alike:
- SMILES linearises the molecular graph as a character string (and one molecule has many valid SMILES).
- IUPAC names follow systematic nomenclature rules built from substituent prefixes and locants.
- InChI is a canonical, layered identifier.
- SELFIES is a token grammar designed so that every string decodes to a valid molecule.
That is a representation-heterogeneity problem in the plainest sense: the same underlying object, several encodings with very different surface statistics. If the model’s answer changes with the encoding, it is responding to the string, not (only) the chemistry. Earlier work had measured this for SMILES versus IUPAC; two things were missing: no study included SELFIES, and none looked inside a model to see where the notation-specific information lives. This paper does both, in two phases.
CCC · propane · InChI=1S/C3H8/c1-3-2/h3H2,1-2H3 · [C][C][C]) gets four different answers spread over 1.7 log S. 1,4-difluorobenzene (Fc1ccc(F)cc1) is a worse case: measured log S −2.636, yet the InChI form is predicted at +1.5, i.e. “highly soluble”: a 6.0 spread and a sign flip. Source: github.com/amethystani/notation-matters · results/phase1_full_results.json; paper/figures/toc_entry.tex| Molecule | Measured | SMILES | IUPAC | InChI | SELFIES | Spread |
|---|---|---|---|---|---|---|
| Propane | −1.553 | −3.0 | −1.5 | −2.3 | −3.2 | 1.7 |
| 1,4-Difluorobenzene | −2.636 | −4.5 | −3.0 | +1.5 | −1.5 | 6.0 |
p-Cresol (Cc1ccc(O)cc1) | −2.313 | −4.6 | +1.4 | −1.2 | −1.5 | 6.0 |
Study design
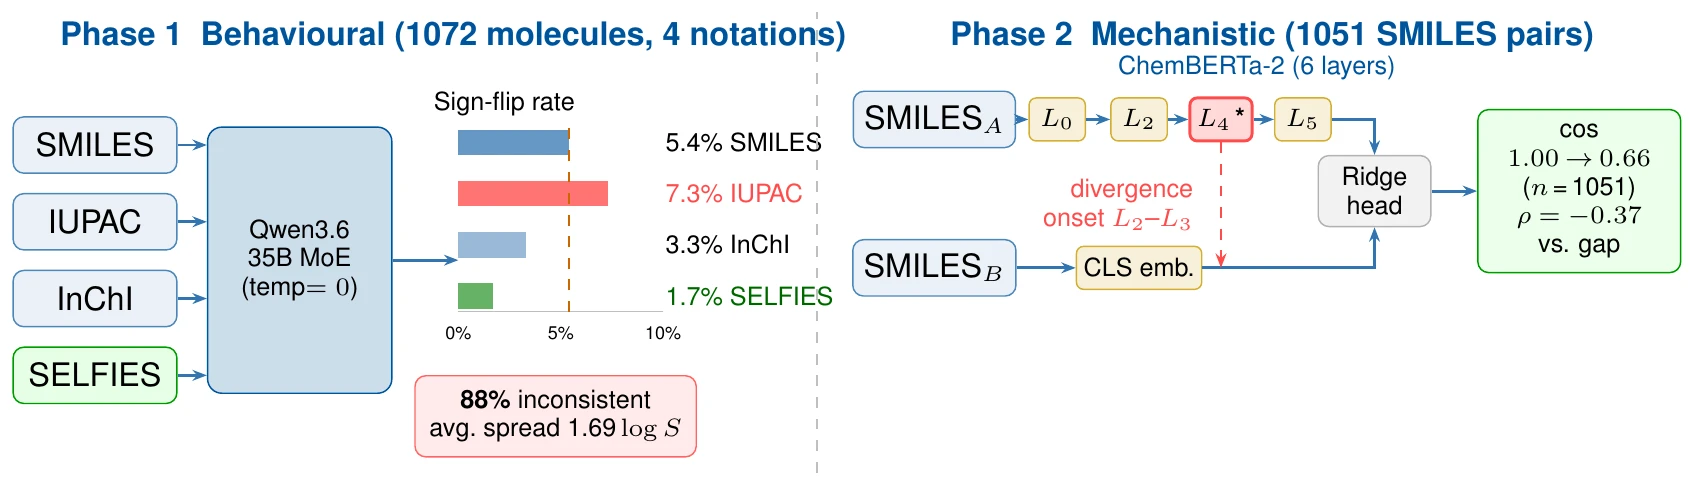
Data: ESOL, and what was lost on the way
The benchmark is ESOL (Delaney 2004), the standard water-solubility set from MoleculeNet: 1,128 molecules with a measured log S (log₁₀ mol/L). SMILES come straight from the dataset. IUPAC names and InChIs are fetched from the PubChem REST service, SELFIES are generated with the selfies library. A molecule is kept if at least two notations return a valid answer, which leaves 1,072; the 56 dropped ones are PubChem lookup failures.
Phase 1: asking one model four ways
The model, and why only one
The reported model is Qwen3.6 (qwen3.6:35b-a3b), a mixture-of-experts model with 35B total and about 3B active parameters, run locally with Ollama in native precision, temperature 0, chain-of-thought disabled, and a 12-token answer limit. It is a general-purpose rather than chemistry-fine-tuned model on purpose, and the MoE design makes deterministic single-workstation runs practical. Four other models were screened and all failed a validity gate:
| Model | Family / precision | Modal fraction | Pearson r | Validity gate |
|---|---|---|---|---|
| qwen3.6:35b-a3b | Qwen3 MoE, native | 21.1% | +0.755 | pass |
| nous-hermes2:34b | Llama, 34 B | 88.8% | +0.197 | fail |
| qwen2.5:7b | Qwen2.5, 7 B | 42.5% | +0.055 | fail |
| hauhau-q4 | Qwen3 MoE, 4-bit | — | — | fail (4/40 parseable) |
| hauhau-iq2 | Qwen3 MoE, 2-bit | 30.8% | −0.177 | fail |
The gate matters more than it looks. Read naively, one rejected model (a 34B Llama variant) “yields 98.9% cross-notation inconsistency and a 0% SELFIES sign-flip rate”, numbers that are pure artefacts of the model answering with a different constant per notation. They are deliberately not reported.
The prompt and the metrics
You are a chemistry expert. Predict the water solubility of the molecule below as logS (log₁₀ molar solubility).

Molecule ({rep}): {mol}

Reply with ONLY one decimal number between -10.0 and 2.0. No text, no units.
Each molecule is queried independently per notation: no history, no few-shot examples, no system prompt. The notation is named in the prompt, so the model always knows what kind of string it is looking at; the divergence therefore comes from notation surface features, not from notation ambiguity.
spread(molecule)  = max(predictions) − min(predictions)   over notations with a valid answer (≥ 2)
inconsistent      = spread > 0.5 log S
sign flip         = true log S < −1  AND  predicted log S > 0        (insoluble called highly soluble)
parse             = first number matching -?\d+\.?\d* ; accept only if −10.0 ≤ value ≤ 2.0 ; one retry
Phase 1 results
The headline
| Analysis set | n | Inconsistent (spread > 0.5) | Mean spread (log S) |
|---|---|---|---|
| All molecules with ≥ 2 valid notations | 1,072 | 88.0% (943) | 1.686 [1.618, 1.757] |
| Three notations only (SMILES, IUPAC, InChI) | 1,012 | 74.9% (758) | 1.244 [1.180, 1.305] |
| Complete cases (all four valid) | 790 | 92.5% | 1.788 |
Across 1,072 molecules the median spread between the highest and lowest of the four answers is 1.3 log S: more than a factor of ten in solubility. Only 45 molecules (4%) received four identical answers. The spread is not a threshold artefact:
Nor is it an artefact of using a range. Replacing max − min by the standard deviation across notations gives a mean of 0.830 log S, and ranks molecules almost identically (Spearman ρ = 0.987). And it is not an artefact of the fine-grained regression framing: collapse the answer to a binary soluble/insoluble call at log S = −2, and on the 790 complete cases 27.8% of molecules still get different verdicts depending on notation.
A split between the average and the disasters
| Notation | n valid | MAE | Sign flips | Pearson r | Spearman ρ | Modal answer |
|---|---|---|---|---|---|---|
| SMILES | 969 | 1.127 | 5.4% | 0.726 | 0.776 | 19.9% say −4.5 |
| IUPAC | 1,000 | 1.038 | 7.3% | 0.774 | 0.831 | 13.0% say −4.5 |
| InChI | 993 | 0.887 | 3.3% | 0.753 | 0.829 | 20.1% say −4.5 |
| SELFIES | 958 | 1.136 | 1.7% | 0.617 | 0.662 | 23.7% say −1.5 |
Two different notations win two different games. SELFIES minimises catastrophic errors, plausibly because its validity-by-construction grammar prevents the model from reading syntactically impossible token sequences; the paper states this as a hypothesis it continues to hold, not a result. InChI minimises average error. The benefit is not portable either: on the second dataset that passed the validity gate, FreeSolv hydration free energy, InChI goes from best on ESOL to worst of three (MAE 3.054 vs 2.596 for SMILES), and 81.9% of molecules still exceed a 0.5-unit spread. Lipophilicity, BBBP and BACE failed the validity gate, so nothing is claimed about them.
The control: a model that cannot be fooled by strings
Which molecules go wrong
Splitting by structural class (assigned by priority-ordered SMILES patterns) shows where the disasters concentrate.
The most inconsistent class is carboxylic acids and esters (mean spread 2.15, Kruskal–Wallis H = 42.85, p = 1.2 × 10⁻⁷). A careful follow-up in the paper narrows that: of 123 molecules containing a C(=O)O group anywhere, the effect lives in the 51 ring-free ones (2.15), not those with an aromatic ring (2.02) or heterocycle (1.45). The honest statement is “a property of ring-free carbonyl compounds”, and the paper declines to pin it on notation surface features alone.
A bug found by a referee, and why it matters
Peer review caught a defect in the first version’s class labelling. The halogen test was written as a regular-expression character class, which matches any single letter in the set, including the capital C that appears in nearly every SMILES string:
Because the classifier is a priority chain, only the labels after the halogen rule moved, and nothing about the model’s predictions changed, so the 88% and the 1.69 are untouched. What changed is the interpretation: with 264 non-halogenated molecules sitting in the “halogenated” bucket, the real danger of halogens was diluted away. With the corrected seven classes, halogenated molecules turn out to be the most sign-flip-prone class overall, and the earlier claim that SELFIES is safest there reverses. The fix is in reclassify_results.py.
Phase 2: where do the strings drift apart?
Phase 1 shows the symptom in a large LLM. Phase 2 looks for the mechanism in something small enough to open up: ChemBERTa, a 6-layer, 768-wide RoBERTa encoder trained on ZINC SMILES. Being SMILES-only, it cannot be fed four notations, so the paper builds pairs of two SMILES strings of one molecule by rotating a SELFIES token sequence by one position and decoding back, and reports that the retained pairs were checked to encode the same molecular graph (1,051 valid pairs from 1,128 attempts).
For each pair, the CLS-token hidden state is read at all seven positions (the embedding output plus six layers) and compared by plain cosine similarity (not CKA, not probes). The curve falls steadily: no single layer is responsible. The largest drops are L1→L3 and the final layer. At the final layer, the cosine is related to the downstream disagreement: pairs with lower cosine have bigger prediction gaps (Spearman ρ = −0.371, p = 1.4 × 10⁻³⁵), and the mean gap rises from 0.324 log S in the most similar fifth of pairs to 1.129 in the least similar fifth.
Can you repair it? A hidden-state replacement test
Divergence is a correlation. To probe whether the diverged state carries the disagreement, the paper runs a replacement experiment, deliberately not called “causal”: during the forward pass of string B, overwrite the CLS state at layer k with string A’s state, then let a Ridge regression head predict log S and see whether the two predictions move together.
# patch layer k of the SMILES_B forward pass with the SMILES_A state, then read out with the Ridge head
Δ(k) = |ŷ_A − ŷ_B| − |ŷ_A − ŷ_B^(k)| # positive = the patch narrowed the gap| Layer | True partner | Random molecule | Reversed | Canonical (own state) | Pairs made worse |
|---|---|---|---|---|---|
| L1 | −0.006 | −0.076 | +0.008 | 0.000 | 49.1% |
| L2 | −0.012 | −0.223 | −0.086 | 0.000 | 50.0% |
| L3 | +0.089 | −0.458 | −0.092 | 0.000 | 44.1% |
| L4 | +0.038 | −0.688 | −0.009 | 0.000 | 45.7% |
| L5 | +0.096 | −0.826 | +0.000 | 0.000 | 42.9% |
- The effect is real but small. Significant at L3 (p = 6.1 × 10⁻⁶) and L5 (p = 4.7 × 10⁻⁵) after Bonferroni correction, marginal at L4, absent at L1 and L2.
- It is specific. The true partner beats a random molecule at every layer, in 58.7% of pairs at L1 rising to 75.5% at L5.
- It is not an artefact of the machinery. The canonical control is exactly zero for all 1,051 pairs.
Consistency is not accuracy
Finally, are inconsistent predictions just inaccurate ones? Measured per pair, the gap between the two predictions has essentially no relationship with the absolute error (Spearman ρ = −0.059, p = 0.055, n = 1,051). Being consistent and being right are separate properties, which is why fine-tuning for accuracy alone should not be expected to fix notation sensitivity. (A non-significant result is a failure to reject, so the paper’s word “orthogonal” is best read as “no detectable dependence at this sample size”.)
What to do with this
- Match the notation to the error you fearSELFIES for fewest catastrophic sign flips (heterocyclic 0/378, carboxylic/ester 0/51, aromatic 1/267); InChI for lowest average error and for alcohols/phenols; SMILES over SELFIES for halogenated compounds; avoid IUPAC names there (36.2% sign flips).
- Say which notation you usedIt is a methods-section variable, not a detail. The same model on the same molecule gives different answers.
- Do not treat single-notation accuracy as molecular understandingA model can be accurate in one notation and inconsistent across them. Test consistency separately.
- Aim for convergence, not agreementCross-notation losses applied across intermediate layers, or a multi-notation encoder, target the representation rather than just matching outputs.
What this paper does not claim
- That any notation is universally best; the ranking is task-dependent and does not transfer to FreeSolv.
- That the effect holds for chemistry-fine-tuned models, other LLMs, or classification tasks. One model passed the gate; the others failed it, and no hosted API model was evaluated.
- That the encoder in Phase 2 is the Phase 1 model; it is a different, much smaller model, and the Phase 2 pairs are within-SMILES rather than true cross-notation pairs.
- Formal causal mediation. The experiment is a representation-level replacement.
- That the descriptor model is better overall; it is more accurate, and the argument is only about consistency.
Code map and how to run it
| Script | Role |
|---|---|
src/notation_benchmark.py | Phase 1: classify, fetch IUPAC + InChI from PubChem, encode SELFIES, query the LLM in four notations, compute spreads, sign flips, MAE, Fisher and Kruskal–Wallis; checkpoints every 25 molecules |
src/reclassify_results.py | Relabel Phase 1 rows with the corrected classifier and recompute class statistics (no new inference) |
src/mechanistic_analysis.py | Phase 2: SELFIES-rotation pairs, ChemBERTa CLS states at seven positions, Ridge head, per-pair cosines, hook-based hidden-state replacement |
src/model_validity_probe.py | The validity gate: 40 random molecules × 4 notations; pass iff modal fraction ≤ 50% and |r| ≥ 0.30 |
src/second_model_benchmark.py | Same protocol on another open model, with failure accounting by cause |
src/multidataset_benchmark.py | The protocol on FreeSolv, Lipophilicity, BBBP and BACE |
src/build_notation_cache.py | Fetch IUPAC/InChI once with polite pacing and backoff so rate limits are not mistaken for model failures |
pip install -r requirements.txt     # numpy scipy scikit-learn pandas requests selfies torch transformers rdkit
ollama pull qwen3.6
bash run_benchmark.sh                   # builds the notation cache, then runs Phase 2 and Phase 1
Phase 1 takes roughly 5–8 hours and Phase 2 1–4 hours on a single workstation. The repository deposits the Phase 1 result files; the Phase 2 outputs, the RandomForest baseline code and the second-dataset outputs described in the paper are not in the public repository. Citation: Animesh Mishra, Notation matters: cross-representation inconsistency in chemistry language models and its mechanistic origins, Digital Discovery, 2026, DOI 10.1039/D6DD00309E.